
← LLM
OpenAI
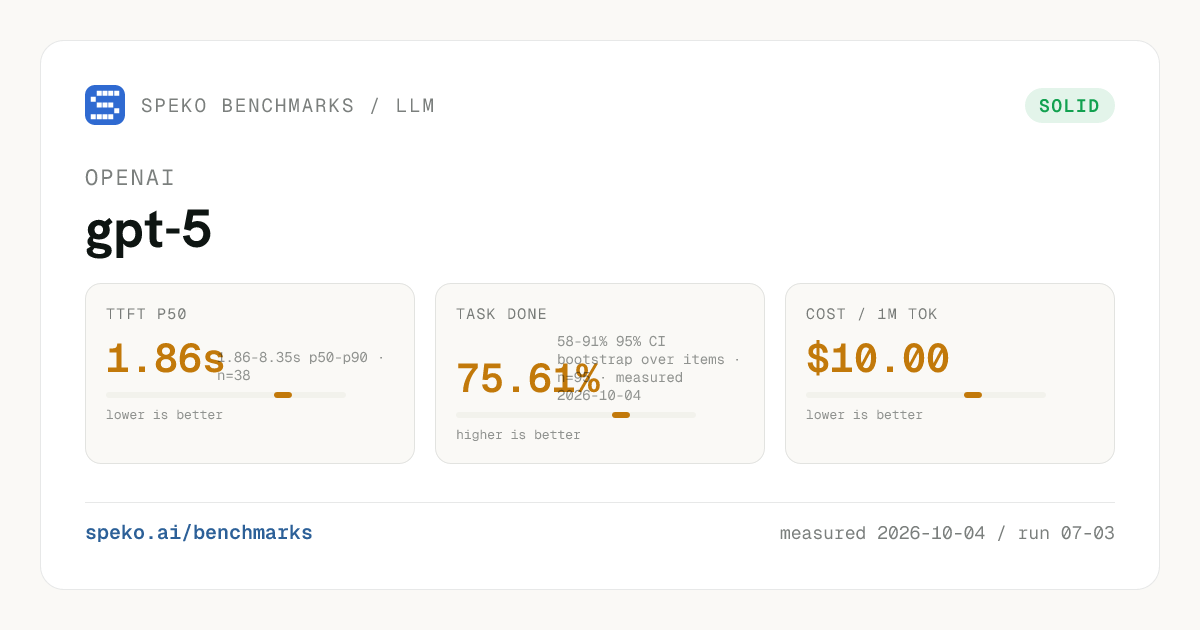
gpt-5
reasoning
Measured 2026-10-04
Build voice agents on Speko →gpt-5 is measured here for comparison — it is not one of the models Speko routes.
Score
40
Task done
75.61%
58–91% 95% CI bootstrap over items · n=95 · measured 2026-10-04
Refusal quality
84.4%
names the gap 77% · offers a route 77% · 10 probes x 3 iterations
Fabrication
7%
2 of 30 probe runs
Dead-air
69.5%
223 of 321 turns
Tool silence
100.0%
all of 19 items (223 tool-call turns) · ≥82%
Stalled
24.4%
22 of 90 runs
TTFT p50
1.86s
1.86–8.35s p50–p90 · n=38
Cost / 1M tok
$10.00
Share this result
Embed the live badge
Markdown
[](https://speko.com/benchmarks/llm/openai-gpt-5)
HTML
<a href="https://speko.com/benchmarks/llm/openai-gpt-5"><img src="https://speko.com/benchmarks/badge/llm/openai-gpt-5.svg" alt="Speko llm rank"></a>
URL
https://speko.com/benchmarks/llm/openai-gpt-5